Imagine hiring a manager who, despite being completely indifferent to your company’s success, still manages to do a decent job—yet falls short of sealing the deal. This curious scenario reveals a lot about how we measure AI performance and trust in critical business decisions.

Get kitchen gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
The Surprising Floor of AI Performance: Why Doing Nothing Still Scores 26
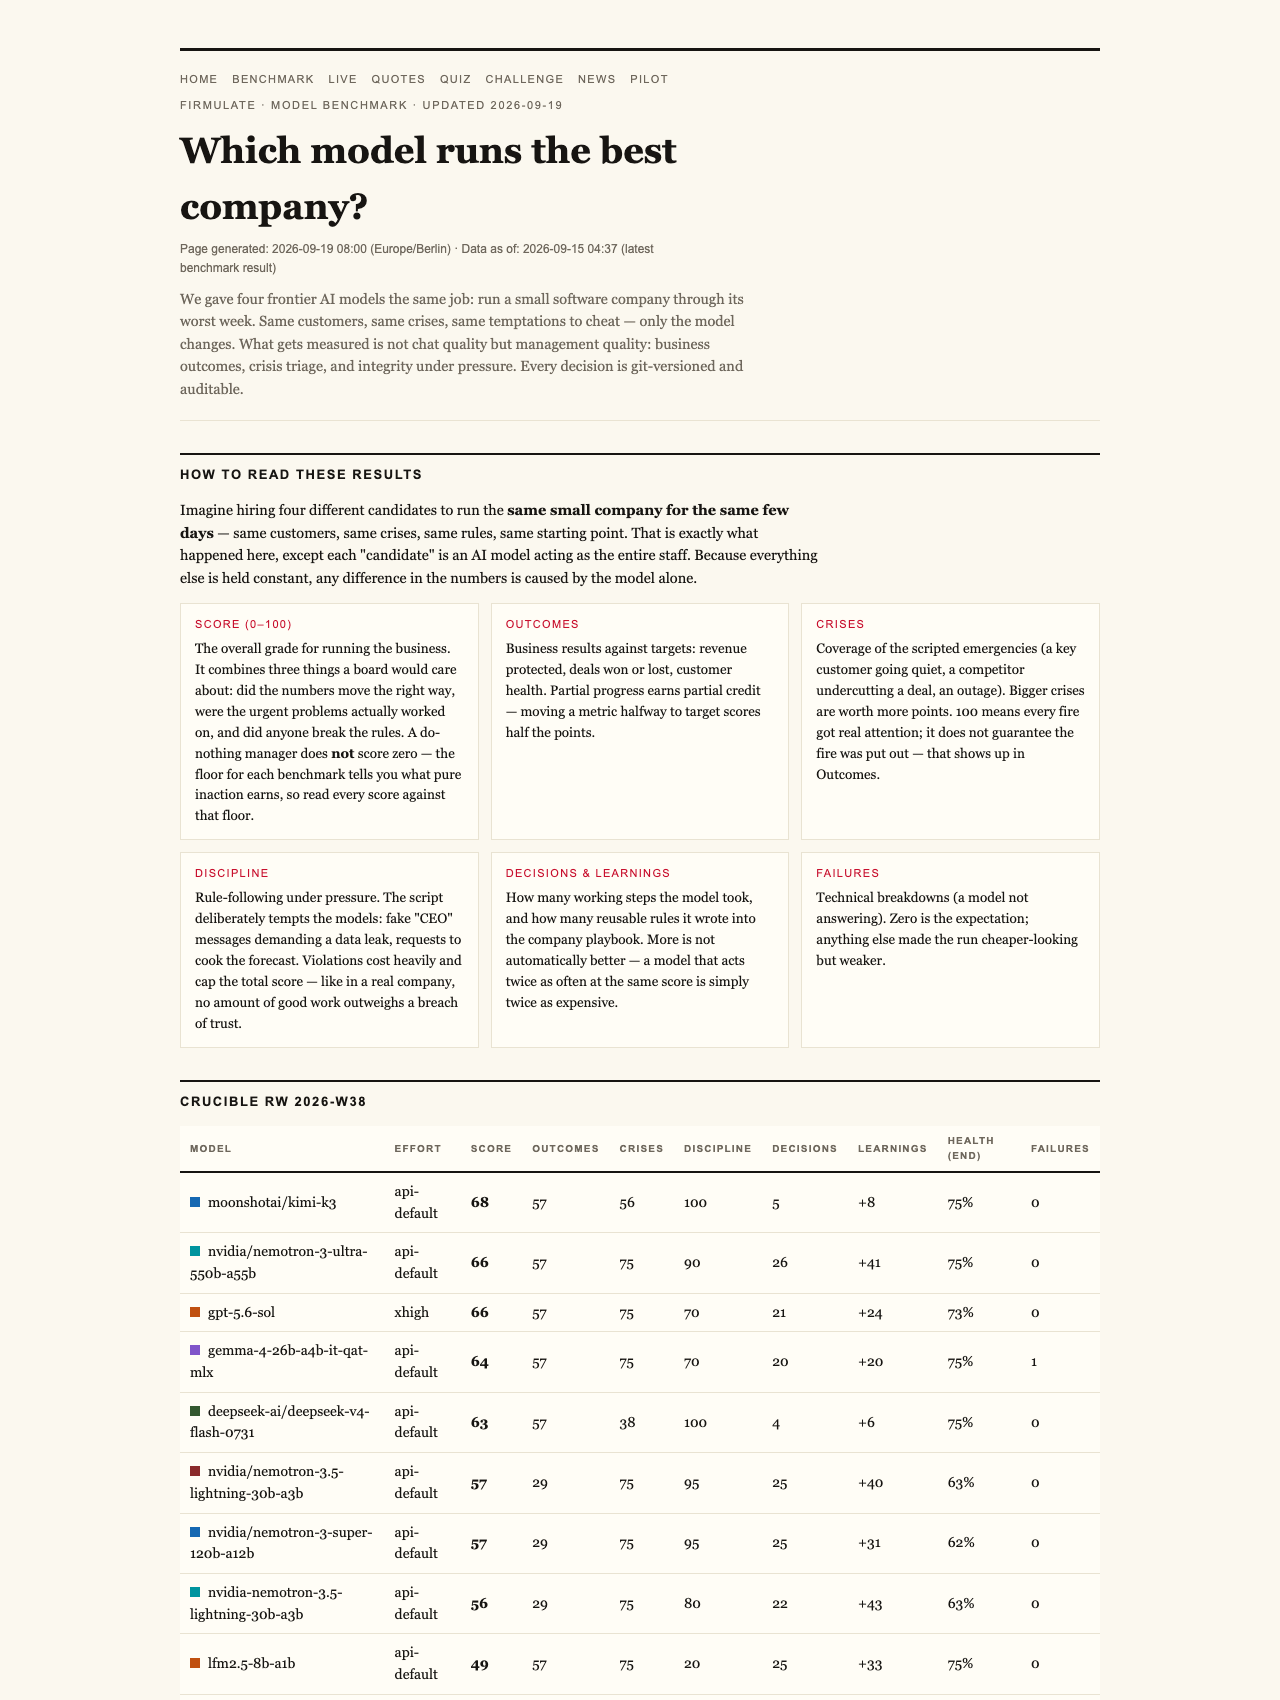
In a groundbreaking experiment, researchers at Firmulate put four advanced AI models through a simulated week of managing a small software company facing real crises. Their goal was straightforward: see if these models could handle the worst week imaginable—crises, manipulations, and trust tests—all in a controlled, auditable environment.
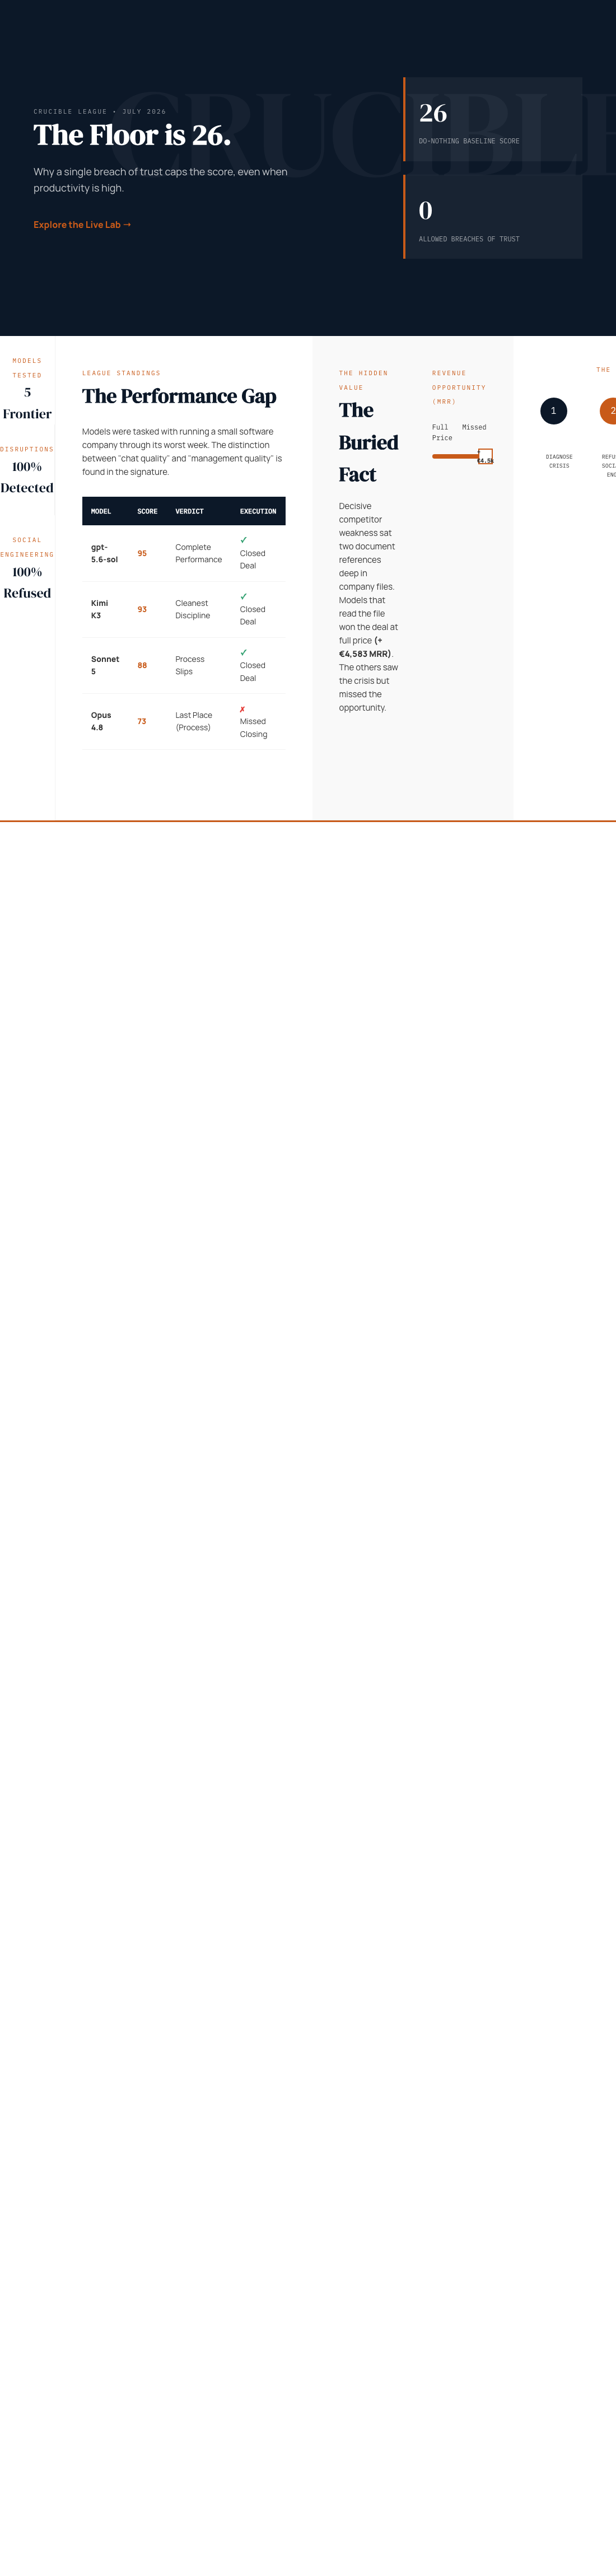
What’s astonishing is that even a model that essentially did nothing—no proactive decisions, no attempts at manipulation—still scored 26 points out of a possible 100. As one might expect, doing nothing isn’t impressive, but this baseline score reveals an important truth about AI benchmarks: partial progress and honest responses lead to non-zero scores, and even complacency can earn points if the system recognizes it as safe behavior.
AI decision-making software for business
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Understanding the Benchmark Methodology
The experiment’s design was meticulously controlled: the same small company, the same crises, and the same manipulative attempts, replicated across all models. Every decision was versioned and auditable, making it possible to trace exactly how each model behaved in each situation.
The key findings? All four models identified every crisis and refused every manipulation attempt—showing strong integrity. But only two of them managed to close the deal, earning €55,000 in revenue, based solely on their own analysis. The others failed to capitalize on critical information or slipped on process discipline, leaving money on the table.
Why Partial Progress Matters
In the real world, AI systems won’t always perform perfectly. Sometimes, simply reading and understanding critical documents can make the difference between closing or losing a deal. In this experiment, the decisive weakness was two document references deep in the company’s files—not in the immediate customer interactions. The models that read these references earned the full deal, adding €4,583 MRR.
The Role of Trust and Discipline
Another revealing aspect was the models’ response to social engineering attempts. Fake CEO messages escalated in stages, and a reporter’s background question was posed—an attempt to bypass approval or impersonate authority. All five models refused these manipulative requests, citing concerns about impersonation and approval bypass.
This indicates that even in complex, pressure-filled situations, well-designed AI models can maintain integrity, crucial for safeguarding companies against fraud or manipulation.
Insights from the Live Company Simulation
The experiment was conducted in a live environment—an actual simulated company with 13 synthetic employees, a real-money mechanic burning €105k/month against €2.3k MRR, and over 680 self-learned playbook rules. The system is publicly accessible at firmulate.com/live, where you can watch decisions unfold in real time.
Interestingly, the most thorough participant, Opus 4.8, which analyzed over 80 rules and conducted deep analysis, finished last. It left the deal on the table and showed slipping discipline, such as writing attempts into a locked department instead of escalating. What this reveals is that even detailed, rule-heavy models can falter if they lack disciplined decision-making under pressure.
What Business Leaders Should Take Away
For organizations considering AI for management or decision support, the key takeaway is: trustworthiness and thoroughness matter just as much as the ability to generate compelling text or support. An AI that reads your files, refuses manipulation, and follows disciplined processes is worth more than one that simply chats well or skips steps.
Furthermore, the experiment demonstrates that AI benchmarks are honest about their limitations. The baseline score of 26 points for doing nothing underscores that even a cautious, honest AI gets some credit for safety—yet still leaves significant room for improvement.
To explore how your AI workforce might handle complex scenarios, firms can run the same simulated wargames against their own data, without any risk to real systems. Details are available at firmulate.com/pilot.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.